Executive Summary
This article reads a speech Governor Christopher J. Waller of the Federal Reserve gave on October 1, 2026, at FRED Con 2026, hosted by the Federal Reserve Bank of St. Louis under the banner "Navigating Trust, AI and Storytelling in a World of Data." He called it "The Data Version of Godzilla versus Kong: FRED Takes on AI." FRED, the Fed's public economic data site, now holds more than 850,000 data series, and Waller told the room that about half the visits arriving there are no longer people but AI agents. The FRED team released a connector the same day that lets an agent reach the data directly.
One more number sits beside that one. FRED traffic sped up once AI arrived and now runs at 150 percent a year, most of the increase coming from AI and bots. A share of current visits and a share of recent growth are two different statements, and laying them over each other gives the picture: machine readers are stacking on top of human ones, fast. Waller's posture toward those machine readers was closer to welcome than to alarm. Agents have generally been very accurate at describing visualizations and unpacking difficult terms, he said, before naming the place where things slipped. In testing, agents have sometimes credited a number to FRED instead of to the agency that produced it.
Sections 1 through 4 stay with what the speech and the American Banker report say. Section 5 reads them through the eyes of someone who works with data. That reading is ours.
Key Numbers
Source: Waller, C. J. (2026). Speech at FRED Con 2026, Federal Reserve Board.
About 50%
Share of FRED visits coming from AI agents
Visits where a person opened a page and visits where a machine retrieved data now split roughly down the middle
150% a year
Current rate of traffic growth
Most of that growth comes from AI and bots. Not the same figure as the share above
865 → 850,000+
Data series hosted on FRED
865 when FRED became a website in 1995, more than 850,000 today
18 million
Unique FRED users in 2025
The same site drew about 6,000 users a week when it launched in 1995
Half the Visits to FRED Are Not People
FRED is the public economic data site run by the Federal Reserve Bank of St. Louis. It gathers U.S. unemployment, prices, interest rates, gross domestic product and thousands of other series in one place where anyone can chart them and download them, which is why it shows up so often as the credit line under a chart in an economics story. Waller began not with the web but with the mail. In 1961, St. Louis Fed research director Homer Jones started mailing a typed weekly digest of economic data from various government agencies to Fed policymakers and staff, academics, journalists and anyone else who asked. A telephone answering machine later took calls from people who could not wait for the post, and in 1991 the data went up continuously on a computer bulletin board reached by dial-up modem. FRED became a website in 1995, with 865 data series and about 6,000 users a week.
Today it hosts more than 850,000 series, and 18 million unique users came through in 2025. All of that is the ordinary growth curve of a public data service over six decades. The weight of the speech falls on what comes next. FRED traffic has always tended to grow each year, but the pace picked up after AI arrived, and it is presently growing 150 percent a year, with most of that growth coming from AI and bots. About half of visits to FRED are now AI agents retrieving data, with the other half, in Waller's phrase, from flesh-and-blood visitors.
The two numbers should not be blended. The first describes who is driving the new traffic; the second describes how everything arriving right now divides up. Read together, the first is pushing the second. Half is not the result of human users drifting away. It is the result of machine users piling on.
▲ The figures Waller disclosed at FRED Con 2026, gathered onto one screen.
There is also the matter of who gave the figure. It is not an outside analyst's estimate but a number the organization that publishes the data read off its own server logs. A public statistics body conceding in a formal setting that half its readership is machinery is still a rare thing to hear this plainly.
The Connector the Fed Opened the Same Day
The FRED team introduced the FRED MCP Connector that day, built to simplify connecting FRED data with AI systems, with a demonstration scheduled at the conference a few hours later. MCP stands for Model Context Protocol, a common specification an AI model uses to reach outside data and tools. In human terms it is less like reading a web page and more like taking a numbered ticket at a counter and being handed the document you asked for. The agent no longer scrapes figures off a rendered screen. It receives, in a defined format, which series exist and what each value means.
The FRED staff calls the arrangement BYOAI, for Bring Your Own AI. Building a Fed-branded chatbot was presumably an option; FRED did not take it. Instead a user points whatever agent they already work with at FRED, and FRED answers for the quality of what gets read.
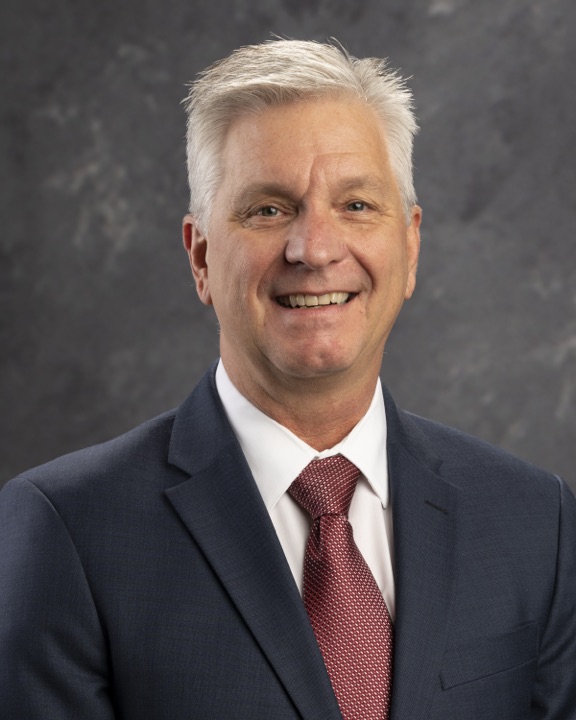
Why is this a big deal, Waller asked himself, and then answered.
"Up till now, FRED has been designed to be viewed and understood by humans. But an AI bot sees and interprets data very differently. And that means the FRED team must adapt how FRED is presented to this new type of viewer so that the data are conveyed back to the agent's master accurately and in a well-documented manner."
Governor Christopher J. Waller, FRED Con 2026, October 1, 2026
The phrase that catches is "this new type of viewer." Adding one more way in would be a smaller announcement than this. What Waller describes is settling the question of how data gets presented on the premise that the reader is a machine. Units, whether a series is seasonally adjusted, when it was last revised: a line of small print under a chart carried all of that well enough for a person. For a machine, it has to travel alongside the value with the same standing as the value.
What the FRED staff named as next steps points the same way. They are developing skills to help agents that visit FRED work with economic data more accurately, and they are building tighter links to FRASER, the archive of historical Federal Reserve material, and to ALFRED, which keeps data as it was first reported and in earlier forms. ALFRED carries particular weight for a machine reader. Economic indicators get revised repeatedly after their first release, and only a record of what was published when keeps a judgment made in the past from being overwritten by today's value.
Waller used the same speech to announce one more thing. Users looking for certain data published by the Federal Reserve Board will soon be routed to FRED and its tools. More numbers will pass through FRED, which makes the job of keeping the distributor's name and the producer's name apart that much heavier.
Agents Write Down the Wrong Home for a Number
Waller did not stop at the good news. The most carefully worded sentence in the speech is an admission.
"FRED's managers don't know whether AI agents are correctly attributing data to the original source, or to FRED, as we have sometimes seen in testing."
Governor Christopher J. Waller, FRED Con 2026, October 1, 2026
Why that sentence is heavy becomes clear once you know what FRED does. FRED does not produce statistics. It is a conduit that collects numbers made elsewhere and ships them out in one consistent format. The unemployment rate comes from the Bureau of Labor Statistics, gross domestic product from the Bureau of Economic Analysis, the policy rate from the Fed itself. FRED puts them side by side so they can be compared. Waller defined its usefulness in exactly those terms.
"[FRED] is a trusted conduit for data from diverse sources because it offers a common platform to access all data in a consistent and reliable way, without a commercial or other parochial interest, following best practices for transparency and reliability. The ultimate credibility of the data lies with those sources that produce the data. But FRED's distribution of the data is a guarantee that it has been accurately reproduced—that what you see is what it claims to be."
Governor Christopher J. Waller, FRED Con 2026, October 1, 2026
Waller split producing from reproducing. Ultimate credibility rests with whoever made the number; what FRED guarantees stops at having carried it over accurately. Those are two different kinds of responsibility. An answer that cites FRED alone collapses them into one name. The party that moved the number appears to have assumed the obligations of the party that made it, and the party actually carrying those obligations goes unnamed.
What breaks when a conduit gets written down as a producer? Verification closes first. An unemployment rate released by the Bureau of Labor Statistics arrives with a survey method, a sample and a revision calendar attached, and confirming any of those definitions means going to a BLS document. An answer that says only FRED leaves the reader stranded there. Accountability blurs next. When a number is corrected, the correction comes from the originating agency, not from FRED. And where the same indicator is published by several bodies under slightly different definitions, losing track of which definition was picked makes the comparison itself unsound.
▲ Where the attribution error Waller described takes place.
None of which should be read one-sidedly. Waller also recorded what the agents did well in the same testing. Despite occasional problems of misattribution, he reported, AI agents have generally been very accurate in describing visualizations and explaining complex terms and concepts in simple ways. What slipped was not the meaning of a number but its birthplace.
The Risks Weigh as Much as the Opportunities
Waller began with the opportunity. "AI can find, summarize, and visualize data more quickly than one person—or even many people—can." With 850,000 series, a person who did nothing but scroll the catalogue would lose a day to it, so the appeal of that speed needs no elaboration. Speed was not the only item on his list. AI can work with much larger quantities of information, he added, and it significantly broadens the audience for data through its searches and by explaining complex concepts to lay users.
He then marked where this technological shift parts from the ones before it. Earlier advances mainly helped distribute data. The mail, the answering machine, the bulletin board and the web all sent the same numbers further and faster without manufacturing any. AI creates content as well, and in Waller's reading that capability is where the new risks begin.
The risk follows immediately, offered as something well known: "AI can hallucinate, introduce bias, and hide key assumptions, often with confidence and polish." Inventing what is not there, importing bias, burying the assumptions that matter, usually in a confident and polished voice. What that means for FRED he spelled out in the same breath. The risk bears on FRED's role as the reliable source of data produced by other organizations, and more narrowly, AI may not accurately cite the sources for data. He listed interpretation errors separately, naming the old headache for economists and statisticians, confusing correlation with causation, which is the jump from two series moving together to one of them moving the other. The more data there is, the more pairs happen to move together.
The shape of the Fed's task comes into focus from there. If attribution keeps breaking and assumptions keep disappearing, the position FRED claims for itself, trusted conduit, starts to wobble. That trust survives only while the numbers passing through still carry their labels on the way out. Opening a connector to make access easy and making sure the answers produced by that easier access are correct are not the same job. The Fed shipped the first and left the second as unfinished business.
American Banker, covering the same speech for a financial industry readership, reduced it to those two tasks: making sure sources are cited accurately, and keeping hallucination, bias and hidden assumptions down. The same questions come back around to whoever is receiving the data.
Why Pebblous Is Watching This Announcement
For a data practitioner, the connector is the smaller of the two things on offer here. The larger one is the change in premise that produced it. For thirty years the reader FRED designed around was a person opening a page to look at a chart. Half of that seat is now occupied by machines, and machines do not look at charts. Waller's own conclusion, to borrow the sentence again, was that the presentation has to adapt to this new type of viewer.
Change that premise and the standard for preparing data changes with it. When a person reads, the reader supplies much of the context. They infer the unit from the chart title, follow the source note with their eyes, and open the originating agency's site when something looks off. A machine reader supplies none of that. Information not handed over with the value simply vanishes, and a model fills the gap with something plausible. The attribution error Waller pointed to is one species of that filling.
Which leaves two questions standing for organizations that are nothing like a central bank. First, who is reading our data right now? Fewer organizations than you would expect can separate human visits from bot visits in their server logs, and fewer still check which direction that ratio is moving on any regular basis. FRED could state a figure of about half because someone was watching the record.
Second, is whoever read it citing the source correctly? That one is awkward to verify, since it happens after the data has left your hands. Work remains on the near side of that departure, though: sending the source, the definition and the time of last update out alongside the value, and checking that all of it is written in a form a machine can read. A source note that exists only as a footnote reaches human readers alone. The skills the Fed is building and the ALFRED links it is wiring up answer the same need.
Public statistics agencies saying out loud that they intend to rebuild their data around machine readers is not yet a common event. The same sequence looks likely at national open data portals and in commercial data products: the share of traffic that is not human becomes visible, an access route opens, and then the question of how to send context and provenance along with the values is left standing as the hard part.
Thank you for reading this far. The full speech is on the Federal Reserve Board site, and the industry read is in American Banker. Take a look at whether your own server logs can separate human visits from machine visits, and whether the data you publish carries its source and definition out alongside the values. We would be glad to hear what turned out to be missing.